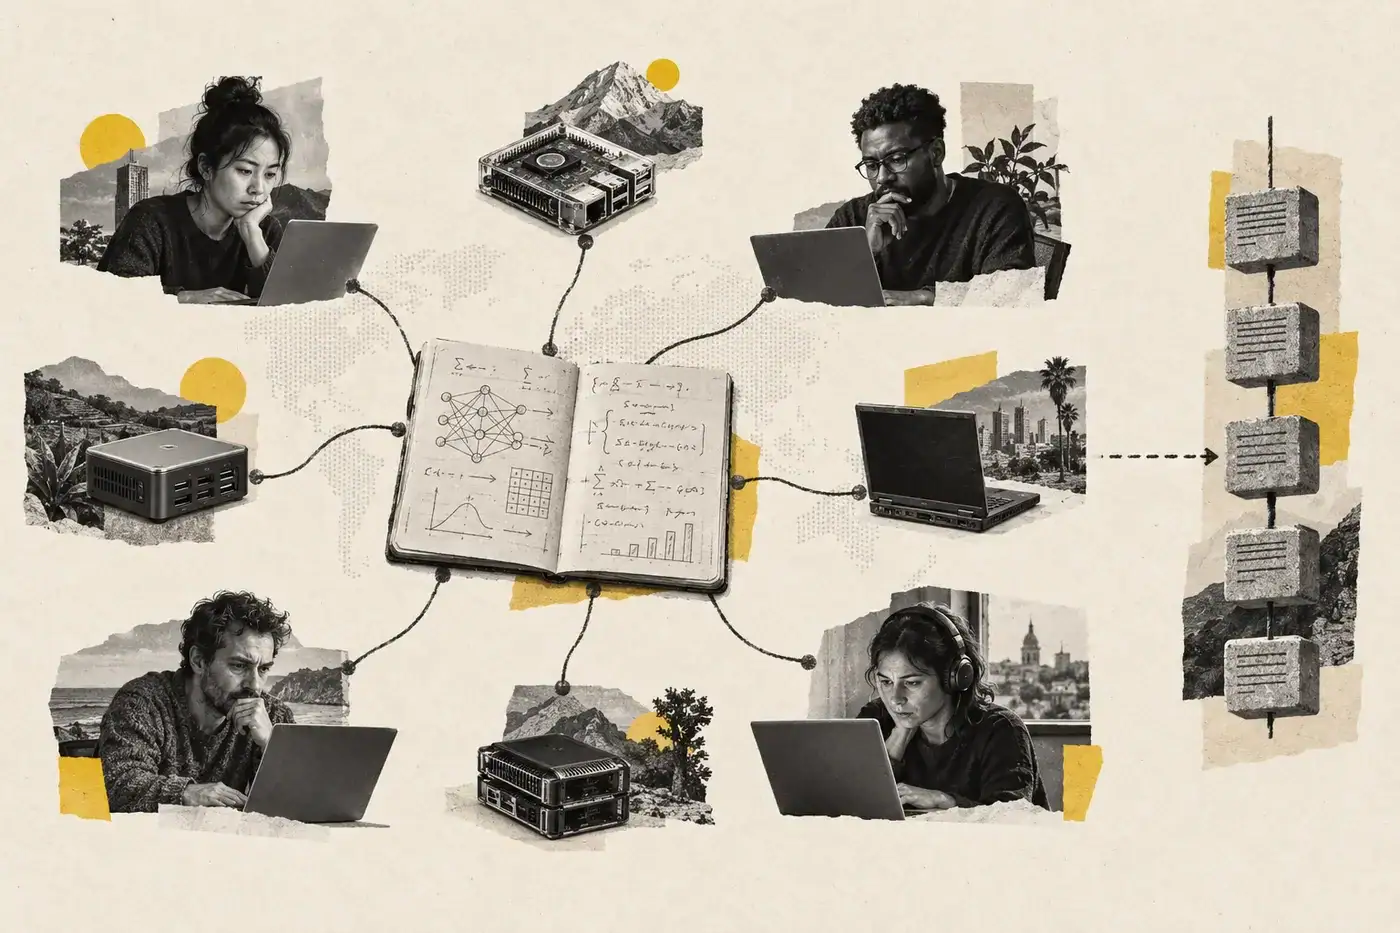
In 2023, I asked ChatGPT to help me turn a loose idea—volunteer computers collaborating on an AI model, with a blockchain coordinating contributions—into Python. The answer looked remarkably complete. It imported libraries, created classes, moved data through a training loop and distributed rewards. There was only one problem: it was not a working system.
That distinction matters more to me now than the original code. The experiment became an early lesson in what generative AI does well: it can give structure to an idea, supply vocabulary and produce something that resembles an implementation. It also showed me what it cannot prove. Coherent code is not the same as executable code, and an architecture that sounds sophisticated is not automatically practical.
A believable answer is not a working system
I do not present myself as a software engineer. What I was doing was closer to reverse engineering a concept: identify the pieces, ask how they might connect and keep prompting until the explanation felt complete. That approach was useful for exploration, but I gave the output more credibility than it had earned.
The prototype referenced secure multi-party computation, a token incentive system, proof-of-work consensus, Ethereum fees and GPT-2 XL. Those terms were real. The imported blockchain, smpc, incentive_system and pow_consensus modules, however, were treated as if complete compatible implementations simply existed. The dataset loader contained only pass. The reward logic had no credible way to determine whether a participant’s contribution improved the model. The training flow did not establish that its tensors, labels or model layers were compatible. It was a sketch wearing the clothes of a program.
The idea underneath it was still interesting
The question I was reaching for remains valid: could spare computing capacity be coordinated so that many people contribute to a shared AI system and receive something in return? Projects such as SETI@home and Folding@home made distributed volunteer computing understandable to the public long before the current AI cycle. Federated learning offers another important pattern: data can remain on participating devices while locally computed model updates are aggregated into a shared model.
That is much closer to a plausible starting point than putting model training “on-chain.” The landmark federated-learning work by McMahan and colleagues describes learning from decentralized data by aggregating locally computed updates. Secure aggregation research then addresses a narrower privacy problem: how a coordinator can calculate an aggregate without reading every participant’s individual update. Neither technique makes trust, quality, security or incentives disappear. It simply defines the problem more accurately.
Where the original prototype breaks
| Prototype assumption | What is missing | A more credible direction |
|---|---|---|
| Store encoded model data in blockchain transactions | Model activations and updates can be large, while permanent on-chain data and computation consume gas | Keep training data and model updates off-chain; record compact hashes, commitments or settlement events only when a shared ledger adds value |
| Fine-tune the final layers on-chain | The EVM is not a practical general-purpose environment for training a 1.5-billion-parameter language model | Train on specialized hardware and verify agreed outputs or attestations separately |
| Use SMPC by calling encrypt and decrypt | Secure protocols require defined participants, threat assumptions, key handling, dropout tolerance and tested cryptography | Start with a proven secure-aggregation protocol and an explicit privacy model |
| Reward contributors listed in a mined block | Presence is not proof of useful work; adversaries can submit duplicated, poisoned or low-quality updates | Define measurable contribution, validation, anti-Sybil controls, dispute handling and the cost of gaming the reward |
| Import custom modules and connect them | The modules, interfaces, tests and failure behavior were never implemented | Build the smallest runnable component first, then test every boundary before adding incentives or governance |
What a more credible architecture might look like
I would now separate the system into layers instead of asking one technology to do everything. Participants would train or process work off-chain on hardware suited to the task. An aggregation layer would combine updates according to a documented protocol. A validation layer would test whether an update is well-formed, safe and useful. A privacy layer would define what participants and coordinators can see. Only then would an incentive and governance layer decide how contributions are recorded, challenged and rewarded.
A blockchain could potentially help where independent parties need a shared, tamper-evident record or automated settlement and do not want one participant to control the ledger. It would not automatically make training decentralized, private, fair or accurate. Ethereum’s own documentation explains that every computation consumes gas and that permanent data storage has explicit per-byte costs. That makes it important to put only the minimum necessary proof or record on-chain, not giant arrays of model data.
Start with the trust problem, not the token
The most difficult part of a collaborative AI network is not issuing a token. It is deciding what deserves a reward. Compute time alone can be wasted. A model update can be technically valid and still damage performance. Contributors may control multiple identities. Private data can leak through updates. A validator can become the new centralized authority the design was supposed to avoid.
So the architecture has to begin with questions that are easy to skip in a concept sketch: Who are the participants? What are they allowed to learn? How is useful work measured? Who can challenge a result? What happens when devices disappear midway through a round? How are poisoned updates detected? What is the simplest trusted arrangement that solves the actual problem?
The lasting lesson was about verification
The original article ended with amazement at what AI could produce. I am still amazed, but for a more precise reason. AI can compress the distance between an unfamiliar idea and a structured first draft. It can help a non-engineer ask better questions and make a concept discussable with people who know how to build it.
That power creates a new responsibility. The more convincing the output looks, the more disciplined the verification has to become. Today I would not paste a generated architecture into an article and treat its completeness as evidence. I would label it as a hypothesis, identify every placeholder, ask an engineer to review the interfaces, run the smallest possible test and publish the results—including the failures.
The prototype did not build decentralized AI. It did something more modest and, in retrospect, more useful: it taught me to separate concept, code and proof.
Context checked September 10, 2026
- GPT-2 XL model card — confirms the 1.5-billion-parameter model and current usage examples.
- Communication-Efficient Learning of Deep Networks from Decentralized Data — the foundational federated-learning architecture referenced here.
- Practical Secure Aggregation for Federated Learning on User-Held Data — defines secure aggregation and its threat model more accurately than the prototype.
- Ethereum gas and fees and blockchain data-storage strategies — current first-party context for computation and storage tradeoffs.